Category: Blog

  • SSR vs CSR vs SSG: Which Rendering Method Wins for SEO and AI?

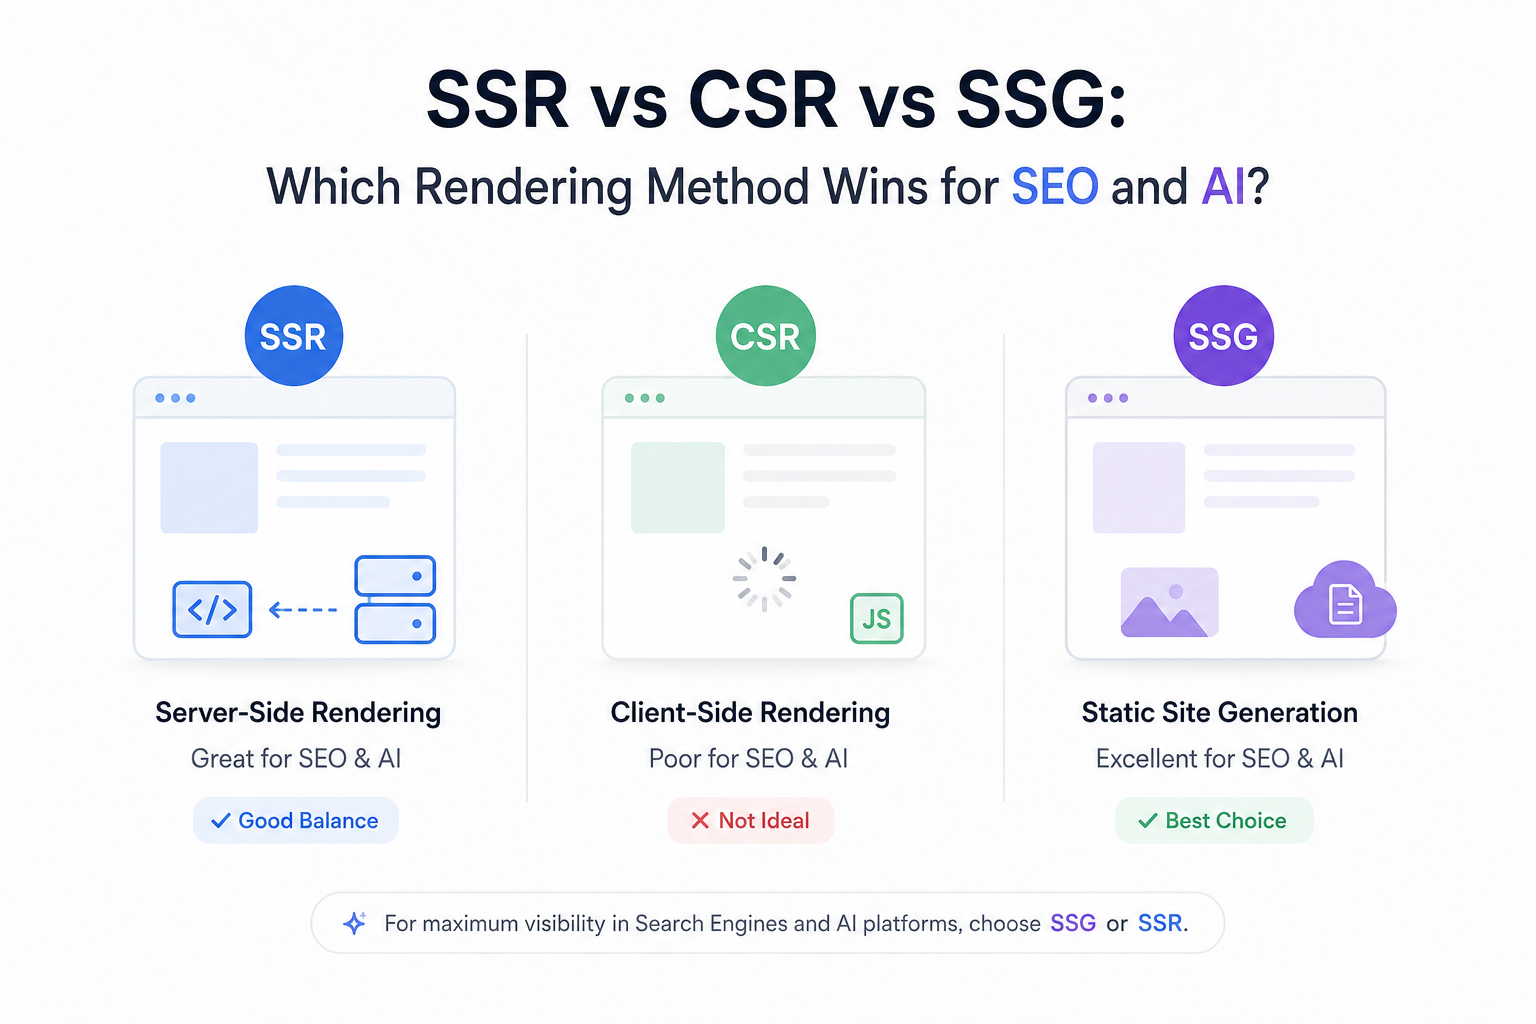
    SSR vs CSR vs SSG: Which Rendering Method Wins for SEO and AI?

    The rendering method you choose for your website is one of the most consequential technical decisions you will make — and it is often made by default rather than by design.

    Most developers reach for what they know. React developers spin up a Vite project and get client-side rendering. WordPress developers get server-side rendering automatically. Teams evaluating Next.js discover they can do all three. And without a clear framework for evaluating these choices, many sites end up with an architecture that works well for developers but performs poorly for crawlers.
    This article gives you that framework. We will define all three rendering methods clearly, compare their performance characteristics, and evaluate each one specifically for SEO and AI search visibility — so you can make the right choice for your situation.


    SSR Explained: Server-Side Rendering

    Server-side rendering (SSR) means the server generates the complete HTML for a page on each request and sends that finished HTML to the browser.

    How It Works

    1. A user (or crawler) requests a URL
    2. The request reaches the server
    3. The server runs application code, fetches any required data, and assembles a complete HTML document
    4. The complete HTML — with all content, metadata, and structured data included — is sent in the HTTP response
    5. The browser displays the page immediately, then loads JavaScript to add interactivity

    The HTML that arrives in the browser is fully populated. There is no waiting for JavaScript to build the page. The content exists in the response from the first millisecond.

    Common SSR Implementations

    • Next.js — getServerSideProps (Pages Router) or async Server Components (App Router)
    • Nuxt.js — Vue-based SSR framework
    • SvelteKit — server rendering with Svelte components
    • Remix — full-stack React framework with SSR by default
    • WordPress — PHP renders complete HTML on every request (the original SSR)
    • Traditional web frameworks — Rails, Django, Laravel, Express with template engines

    Strengths of SSR

    • Complete HTML on first response — fully readable by all crawlers immediately
    • Dynamic content — each request can serve personalized or real-time content
    • Fresh data — the server fetches current data on each request; no rebuild required for content changes
    • Fully crawlable — both Googlebot and AI crawlers receive complete content

    Weaknesses of SSR

    • Server load — every page request requires server computation
    • Latency — the server must finish rendering before the browser receives anything, adding time to the first byte
    • Infrastructure complexity — requires a running server, not just static file hosting
    • Caching required — without caching, high traffic can overwhelm the server

    CSR Explained: Client-Side Rendering

    Client-side rendering (CSR) means the server sends a minimal HTML shell, and JavaScript running in the browser builds the page content after it arrives.

    We covered CSR in depth in the previous article. Here is the summary:

    How It Works

    1. Request arrives at server
    2. Server responds with a near-empty HTML file containing a <div> placeholder and <script> tags
    3. Browser downloads JavaScript bundles
    4. JavaScript executes and builds the page content in the browser
    5. Page becomes visible

    Common CSR Implementations

    • Create React App — CSR by default
    • Vite (with React, Vue, or Svelte) — CSR by default
    • Angular — CSR by default
    • Vue CLI — CSR by default

    Strengths of CSR

    • Rich interactivity — full SPA experience with smooth, app-like navigation
    • Simple hosting — static files served from a CDN, no server required
    • Decoupled architecture — frontend and backend are fully independent
    • Great developer experience — large ecosystems, fast local development

    Weaknesses of CSR

    • Empty initial HTML — no content in the server response for crawlers
    • Poor AI crawlability — AI crawlers receive nothing meaningful
    • Delayed Google indexing — Google’s two-wave rendering introduces indexing lag
    • Slow initial load — users must wait for JavaScript to download and execute before seeing content
    • SEO risk — content-dependent on JavaScript execution is inherently fragile for search visibility

    SSG Explained: Static Site Generation

    Static site generation (SSG) means all pages are pre-built as complete HTML files at deploy time and served directly from a CDN.

    How It Works

    1. At build time, the framework generates HTML for every page (fetching data from APIs, CMSes, or files as needed)
    2. The finished HTML files are deployed to a CDN
    3. When a user (or crawler) requests a URL, the CDN serves the pre-built HTML file instantly
    4. No server-side computation happens at request time — the file is already done

    Common SSG Implementations

    • Next.js — getStaticProps and generateStaticParams (or export const dynamic = 'force-static' in App Router)
    • Astro — SSG-first framework with optional islands of interactivity
    • Gatsby — React-based SSG
    • Hugo — extremely fast SSG (written in Go)
    • Jekyll — the original static site generator
    • Eleventy (11ty) — lightweight, flexible SSG

    Strengths of SSG

    • Fastest possible delivery — pre-built files served from CDN edge nodes globally
    • Perfect crawlability — complete HTML exists before any request is made
    • Lowest hosting cost — static files are cheap to serve at scale
    • Excellent Core Web Vitals — TTFB is typically under 50ms from CDN edge
    • Zero server load at request time — no computation required per request

    Weaknesses of SSG

    • Content requires rebuilds — when content changes, a new build must be deployed for changes to appear
    • Not suitable for dynamic content — personalized pages, real-time data, and user-generated content cannot be truly static
    • Build time scales with page count — sites with tens of thousands of pages can have long build times
    • Preview complexity — content editors cannot preview unpublished changes without a preview environment

    ISR: Incremental Static Regeneration

    Next.js introduced a hybrid called Incremental Static Regeneration (ISR) that addresses SSG’s rebuild limitation. With ISR, pages are pre-built statically but regenerated in the background at defined intervals (e.g., every 60 seconds) or on demand when content changes.

    ISR delivers static-speed performance for most requests while keeping content relatively fresh — without requiring a full site rebuild on every change. It is one of the most practical solutions for large content sites that need both performance and freshness.


    Performance Comparison

    How each rendering method performs for the metrics that matter most to users and crawlers:

    MetricSSRCSRSSG
    Time to First Byte200–800ms50–200ms (shell)20–100ms
    Time to InteractiveFastSlow (JS load)Very Fast
    Largest Contentful PaintGoodPoorExcellent
    Hosting complexityHighLowVery Low
    Infrastructure costMedium–HighLowVery Low
    Scales under trafficNeeds cachingExcellentExcellent
    Content update speedInstantInstantRequires rebuild

    Notes on the table:

    • CSR’s fast TTFB is deceptive — the shell HTML arrives quickly, but it contains no content. Users still wait for JavaScript before they see anything.
    • SSR’s TTFB can be reduced significantly with caching. A CDN-cached SSR response can approach SSG speeds while retaining SSR’s dynamic capabilities.
    • SSG’s rebuild requirement is mitigated by ISR in Next.js and similar approaches in other frameworks.

    SEO and AI Crawlability Comparison

    This is where the architectural choice has the most direct impact on visibility:

    DimensionSSRCSRSSG
    Googlebot crawlabilityExcellentLimited (Wave 2)Excellent
    AI crawler crawlabilityExcellentPoor — near zeroExcellent
    Initial HTML contentCompleteEmpty shellComplete
    Schema markup deliveryServer-renderedRisk of JS dep.Pre-rendered
    Indexing speedFastSlowVery Fast
    Freshness for retrievalHigh (per request)N/A (not crawled)Medium (rebuild)
    Dynamic personalizationFullFullNot supported
    GEO readinessHighLowHigh
    Ideal content typeDynamic, personalizedApps, dashboardsBlogs, docs, marketing

    The Verdict by Use Case

    For a content blog or marketing site: SSG wins. Pages are pre-built, delivered instantly from CDN, fully readable by all crawlers, and require no server infrastructure. Build times for typical blog sizes (under 5,000 pages) are fast enough that rebuilds on content changes are practical.

    For a news site or e-commerce store with frequently changing content: SSR wins. Product prices, inventory, and breaking news need to be current on every request. SSG’s rebuild cycle is too slow for content that changes minute-to-minute. SSR with caching delivers fresh content without the crawlability penalty of CSR.

    For a SaaS product’s marketing and documentation site: SSG or SSR both work. SSG is simpler and faster; SSR offers more flexibility for personalization and A/B testing. Next.js with ISR is a common choice — static by default, regenerated on a schedule.

    For a web application (dashboard, tool, authenticated interface): CSR is appropriate. Crawlability is irrelevant for authenticated pages. CSR’s developer experience advantages and rich interactivity benefits apply here without the visibility cost.

    The rule that applies in all cases: any page whose visibility to search engines or AI systems matters must deliver its content in the initial HTML response. SSR and SSG both satisfy this requirement. CSR does not.


    Choosing Your Rendering Strategy

    The decision is rarely all-or-nothing. Most modern web properties use different rendering strategies for different parts of the site:

    yourproduct.com/          → SSG (homepage, marketing)
    yourproduct.com/blog/     → SSG (content pages)
    yourproduct.com/docs/     → SSG (documentation)
    yourproduct.com/pricing/  → SSR (dynamic pricing)
    app.yourproduct.com/      → CSR (authenticated application)

    This is not over-engineering — it is matching the architecture to the requirement. Each section of the site has different needs: the marketing site needs crawlability and performance, the app needs interactivity and real-time data.

    Next.js makes this particularly practical because it supports SSR, SSG, and ISR within the same framework, with the rendering method defined per page or per route. A single Next.js codebase can handle all of the above.


    The One Rule That Overrides Everything

    Rendering methods come with tradeoffs. Performance, hosting cost, freshness, interactivity — these all vary by approach.

    But for search visibility and AI crawlability, there is one rule that overrides all other considerations:

    Content that does not exist in the initial HTML response does not exist for crawlers.

    SSR puts content in the initial response. SSG puts content in the initial response. CSR does not.

    Everything else — schema markup, internal linking, content quality, keyword strategy, structured data — builds on this foundation. If the foundation is missing, nothing built on top of it will compensate.


    Next: Why Server-Side Rendering Matters for Generative Engine Optimization →

    ← Previous: Why Client-Side Rendered Websites Can Lose Visibility in AI Search

    This article is part of a 20-article series on SEO, GEO, and AI Visibility. View the complete series →
  • Why Client-Side Rendered Websites Can Lose Visibility in AI Search

    Why Client-Side Rendered Websites Can Lose Visibility in AI Search

    Imagine spending months building a React application. The design is polished. The content is thorough. The copy is sharp. You launch, share the URL, and watch human visitors engage with it perfectly.

    Then you ask ChatGPT or Perplexity about the topic your site covers. Your competitor — with a simpler, older-looking WordPress blog — gets cited. You don’t.

    The problem is not your design. It is not your copy. It is not even your content. It is the architecture underneath — specifically, the fact that your content only exists after JavaScript runs in a browser. And AI crawlers don’t run JavaScript.

    This article explains exactly what client-side rendering does, why it creates a systematic visibility gap in AI search, and how to know whether your site has this problem right now.


    What Is Client-Side Rendering?

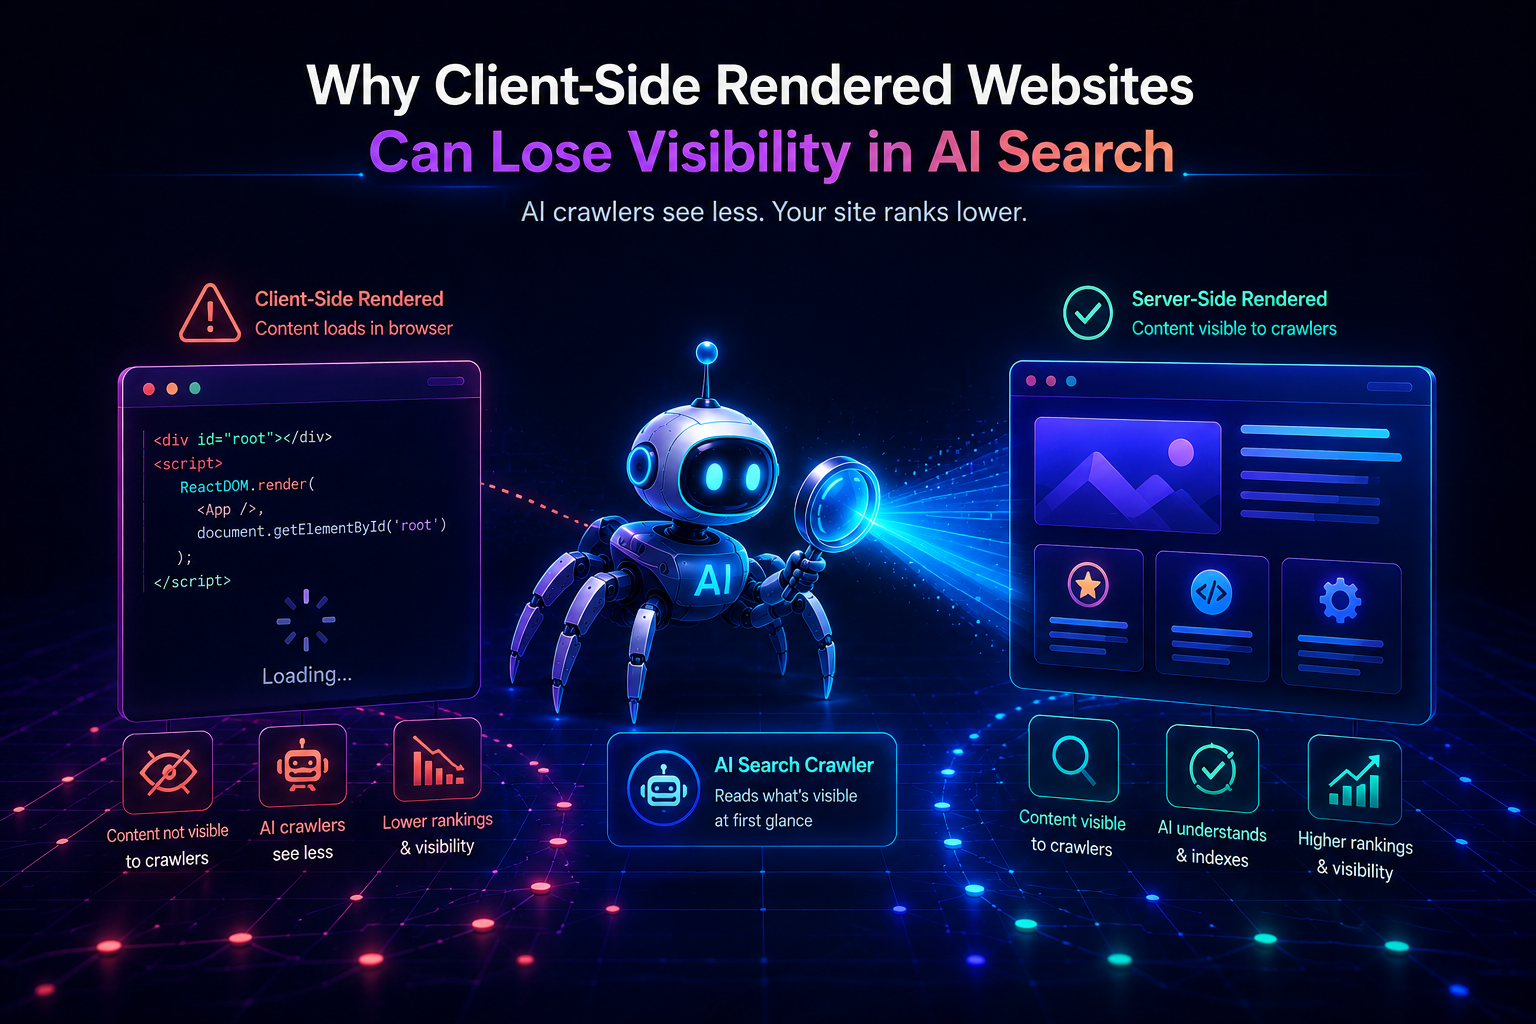
    Client-side rendering (CSR) is a web architecture pattern where the server sends a minimal HTML file to the browser, and JavaScript running in the browser builds the actual page content after it arrives.

    Here is how the process works step by step:

    1. User (or crawler) requests a URL
    2. Server responds with a bare HTML shell containing almost no content — just a <div> placeholder and <script> tags pointing to JavaScript files
    3. The browser downloads those JavaScript files (often several hundred kilobytes to several megabytes)
    4. JavaScript executes in the browser
    5. JavaScript fetches data from APIs if needed
    6. JavaScript builds the page’s HTML and inserts it into the DOM
    7. The page becomes visible and interactive

    The result for a human user in a modern browser: a fast, interactive experience once everything loads. The result for an AI crawler: an empty page.

    Why Developers Choose CSR

    CSR became the dominant architecture pattern for web applications between roughly 2015 and 2022, largely because of the rise of React, Vue, and Angular. The appeal is real:

    • Rich interactivity: SPAs (single-page applications) can update content without full page reloads, creating a native-app-like experience.
    • Clean separation: The frontend and backend are decoupled — the frontend is a JavaScript app, the backend is an API. Teams can work independently.
    • Simple hosting: A CSR app is a folder of static files (HTML, JS, CSS). It can be served from a CDN with no server-side processing required.
    • Developer experience: Frameworks like React and Vue have excellent tooling, large communities, and rich ecosystems.

    These are genuine advantages — in the right context. The problem is that CSR became the default choice for all websites, including content-heavy public pages that need to be crawled and cited.

    Common CSR Frameworks

    FrameworkDefault ModeCommon Use
    Create React AppCSRSPAs, dashboards
    Vite + React/VueCSRSPAs, apps
    AngularCSREnterprise apps
    Svelte (SPA mode)CSRInteractive apps

    The Empty HTML Problem

    The most direct way to understand what AI crawlers see is to look at the raw HTML that a CSR site delivers.

    When a crawler sends an HTTP request to a typical React app built with Create React App or Vite, it receives something like this:

    html

    <!DOCTYPE html>
    <html lang="en">
      <head>
        <meta charset="UTF-8" />
        <title>My SaaS Product</title>
      </head>
      <body>
        <div id="root"></div>
        <script type="module" src="/assets/index-Dj3kL9mN.js"></script>
      </body>
    </html>

    That is the complete server response. The <div id="root"> is empty. The page title is generic. There is no meta description, no H1, no paragraph text, no product description, no blog content — nothing.

    Everything your visitors see — every heading, every paragraph, every product feature, every carefully written explanation — lives inside that JavaScript bundle. It appears in a browser because browsers are designed to download and execute JavaScript. Crawlers are not.

    What a Crawler Extracts from This Response

    From the HTML above, a crawler can extract exactly three pieces of information:

    1. The page language is English
    2. The page title is “My SaaS Product”
    3. There is a JavaScript file at /assets/index-Dj3kL9mN.js

    That is all. No content. No context. No reason to cite this page for anything.

    The Contrast: A Server-Rendered Page

    Compare that to what the same page delivers when server-rendered:

    html

    <!DOCTYPE html>
    <html lang="en">
      <head>
        <title>Project Management Software for Remote Teams</title>
        <meta name="description"
          content="ProductName helps distributed teams track tasks and
          manage deadlines. Trusted by 12,000+ teams worldwide." />
        <script type="application/ld+json">
        {
          "@context": "https://schema.org",
          "@type": "SoftwareApplication",
          "name": "ProductName",
          "applicationCategory": "BusinessApplication"
        }
        </script>
      </head>
      <body>
        <main>
          <h1>Project Management Software Built for Remote Teams</h1>
          <p>ProductName gives distributed teams a single place to track
          tasks, manage deadlines, and communicate without scattered tools.
          Used by over 12,000 teams across 40 countries.</p>
          <h2>Why Remote Teams Choose ProductName</h2>
          <p>Remote work creates coordination problems that office-based
          tools weren't designed to solve...</p>
        </main>
      </body>
    </html>

    From this response, a crawler immediately has: a descriptive page title, a meta description, structured data declaring this is a software application, an H1 with the primary topic, a clear opening paragraph explaining what the product does and for whom, and the beginning of the next section.

    The content is identical in both cases — the difference is entirely in when and where it appears. In the CSR version, it appears only in the browser after JavaScript runs. In the server-rendered version, it appears in the HTTP response before anything else happens.


    SEO Consequences of Client-Side Rendering

    The impact of CSR on SEO is not hypothetical — it is measurable and consistently documented.

    Google’s Two-Wave Rendering Problem

    Google is the most sophisticated crawler on the internet. It does attempt to render JavaScript — but not immediately, and not perfectly.

    Google’s JavaScript rendering works in two waves:

    • Wave 1: Googlebot fetches the raw HTML immediately. It indexes whatever content exists in that response right away.
    • Wave 2: Googlebot queues the page for JavaScript rendering. This rendering happens later — sometimes hours after the initial crawl, sometimes days or weeks later for lower-priority pages.

    The content from Wave 2 eventually gets indexed, which is why CSR sites can still rank on Google. But the delay has consequences:

    • New content indexes slowly. A blog post published today on a CSR site may not be fully indexed for several days, while a server-rendered equivalent is indexed within hours.
    • Content freshness signals are degraded. AI retrieval systems that weight freshness highly may never see your content as current.
    • Crawl budget is consumed less efficiently. Google spends resources rendering pages that could have delivered content immediately.

    The Competitive Disadvantage in Ranking

    Even when Google eventually indexes CSR content, the delay and the extra rendering overhead create a structural disadvantage against competitors with server-rendered sites. For competitive queries where freshness and crawl frequency matter, this gap is meaningful.


    AI Crawlability Challenges

    For AI search systems, the CSR problem is more severe than it is for Google — because AI crawlers do not even attempt JavaScript rendering.

    When GPTBot, PerplexityBot, ClaudeBot, or OAI-SearchBot visits a CSR page, the experience is the same every time: they receive the empty HTML shell, extract no meaningful content, and move on. There is no Wave 2. There is no eventual rendering. The content simply does not exist from their perspective.

    This creates two specific visibility failures:

    Training Data Gap

    AI language models are trained on text scraped from the web. CSR pages that existed before the training cutoff contributed nothing to that training data — because the text they contained was never in the HTML that training crawlers collected. Your content, however good, is absent from the model’s knowledge base.

    Live Retrieval Gap

    For AI search products that use real-time retrieval (Perplexity, ChatGPT Search), a crawler fetches your page at the moment a user asks a relevant question. It receives the empty shell. It finds no content to pass to the language model. Your page is not cited in the answer — not because your content isn’t relevant, but because it was never visible.

    The result: CSR sites are systematically underrepresented in AI-generated answers relative to their actual content quality. A mediocre blog post on a server-rendered WordPress site has a higher probability of being cited than an excellent, comprehensive guide on a CSR React app — simply because the WordPress post is readable and the React app is not.


    When CSR Is Still the Right Choice

    CSR is not inherently bad architecture. It is the wrong architecture for public, content-heavy pages that need to be visible to crawlers. It is the right architecture for many other things.

    Where CSR Is Appropriate

    Authenticated application interfaces — dashboards, admin panels, user account pages, settings screens. These pages are behind login walls, so crawlers cannot access them regardless of rendering method. CSR is ideal here: rich interactivity, no crawlability requirement.

    Internal tools — project management interfaces, analytics dashboards, internal documentation systems. Visibility to search engines or AI systems is irrelevant.

    Highly interactive features — real-time data visualizations, collaborative editing interfaces, interactive simulations. These require the kind of dynamic rendering that CSR enables.

    Where CSR Creates Problems

    Marketing websites — homepages, feature pages, pricing pages, landing pages. These need to be visible to both search engines and AI crawlers.

    Blog and content pages — every article, guide, or resource your team produces. These are the pages most likely to be cited by AI systems, and they need to be fully readable in the server response.

    Product pages and category pages — for e-commerce or SaaS, these pages are the core of organic visibility.

    The Industry-Standard Solution

    Most mature product organizations solve this with hybrid architecture: CSR for the application (the authenticated, interactive product interface) and SSR or SSG for the public-facing content (the marketing site, blog, documentation).

    The marketing site and the product are separate codebases, often on separate subdomains (yourproduct.com for marketing, app.yourproduct.com for the application). Each is built with the architecture appropriate to its purpose.

    This is not a workaround — it is the standard approach used by companies whose products are themselves built in React or other CSR frameworks. They understand the distinction between the application and the content that markets it.


    How to Diagnose Your Own Site

    If you are unsure whether your site has a CSR visibility problem, these tests will tell you in minutes.

    Test 1 — The curl test:

    bash

    curl -s https://yoursite.com | grep -i "<h1\|<p\|<article"

    If this returns nothing, your main content is JavaScript-rendered and invisible to AI crawlers.

    Test 2 — Disable JavaScript: Open Chrome DevTools → Command Palette (Cmd+Shift+P) → “Disable JavaScript” → reload the page. If your page goes blank or shows only a loading spinner, you have a CSR problem.

    Test 3 — View source: Right-click on your page → “View Page Source” (not Inspect — that shows the rendered DOM). Search for a sentence from your main content. If it does not appear, that content is JavaScript-rendered.


    The Core Principle

    CSR is a powerful tool that solves real problems — for applications. For public content pages, it creates a structural invisibility that no amount of content quality, keyword optimization, or link building can compensate for.

    The fix is not to abandon JavaScript frameworks. It is to understand where rendering needs to happen: on the server, before the crawler arrives, for every page whose visibility matters.


    Next: SSR vs CSR vs SSG: Which Rendering Method Wins for SEO and AI? →

    ← Previous: What AI Crawlers Actually See When They Visit Your Website

    This article is part of a 20-article series on SEO, GEO, and AI Visibility. View the complete series →
  • What AI Crawlers Actually See When They Visit Your Website

    What AI Crawlers Actually See When They Visit Your Website

    If you’ve been paying attention to the search landscape in 2026, you’ve probably started asking a version of the same question: Do I focus on Google, or do I focus on AI search?

    It’s the wrong question — but it’s an understandable one. The two systems look different, behave differently, and reward different things. Treating them as competing priorities, however, is a mistake that leads to underinvesting in both.

    The right question is: How do Google SEO and AI SEO differ, where do they overlap, and how do I build a strategy that serves both?

    This article answers all three. By the end, you’ll understand exactly how each system finds and evaluates content, what the shift from ranking to citation means in practice, and why the most effective digital strategies in 2026 treat AI SEO not as a replacement for traditional SEO but as a required layer on top of it.


    How Google Finds Content

    Google’s process for surfacing content has three distinct stages: crawling, indexing, and ranking. Understanding each stage clarifies what traditional SEO is actually optimizing for.

    Crawling

    Googlebot — Google’s automated web crawler — discovers pages by following links across the internet and reading XML sitemaps that websites submit. When Googlebot visits a page, it downloads the HTML (and, with a delay, attempts to render any JavaScript) and stores that raw content for processing.

    The practical implication: pages that aren’t linked to, aren’t in sitemaps, or are blocked by robots.txt rules simply don’t enter Google’s awareness. Crawlability is the prerequisite for everything else.

    Indexing

    Once crawled, Google’s systems analyze the page’s content — text, structure, metadata, images, links — and store it in Google’s index, associating it with the topics and queries it appears to address.

    Not every crawled page gets indexed. Pages that Google considers low-quality, duplicate, or irrelevant may be crawled but never stored in its index. Only indexed pages can compete in search results.

    Ranking

    When a user submits a query, Google’s ranking algorithms evaluate every indexed page relevant to that query and assign positions based on hundreds of signals. The most significant include:

    • PageRank and backlinks: How many credible external sites link to this page, and what is the authority of those sites?
    • E-E-A-T: Does the content demonstrate Experience, Expertise, Authoritativeness, and Trustworthiness?
    • Relevance: How closely does the page’s content match the user’s query intent?
    • Core Web Vitals: Does the page load quickly, remain visually stable, and respond promptly to interaction?
    • Freshness: For time-sensitive queries, how recently was the content published or updated?

    The outcome of this process is a ranked list of links. Users see results, evaluate them, and choose where to click. Traffic flows from Google to your page.

    What Google rewards, in summary: relevance to the query, authority signals from backlinks and E-E-A-T, technical quality, and freshness where applicable.


    How AI Assistants Find Information

    AI-powered search systems — ChatGPT Search, Perplexity AI, Google AI Overviews, Microsoft Copilot, Claude — work through a fundamentally different process. There are two mechanisms at play, and most AI search products use a combination of both.

    Trained Knowledge

    Large language models (LLMs) are trained on enormous datasets of text gathered from across the internet, books, academic papers, and other sources. This training process encodes a vast amount of factual knowledge directly into the model’s parameters.

    When a user asks a question, the model can answer from this trained knowledge without consulting any external source. The information it has access to, however, is frozen at its training cutoff date — it does not update in real time.

    Live Retrieval

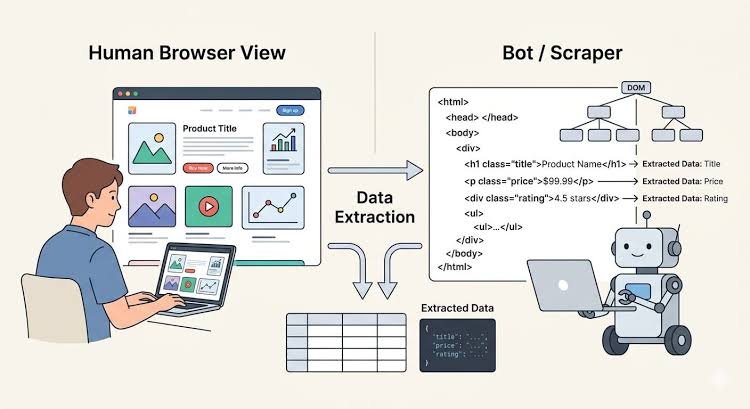
    To address the freshness problem and to ground answers in current sources, most AI search products layer a retrieval system on top of trained knowledge. At query time, a crawler fetches relevant pages from the web, extracts their content, and passes that content to the language model as context for generating the answer.

    This is how GPTBot (OpenAI), PerplexityBot, ClaudeBot (Anthropic), and Bingbot operate in the context of AI search products. They are not indexing pages for later ranking — they are fetching pages at the moment a user asks a question, to inform the answer being generated right now.

    The Critical Difference: Synthesis, Not Links

    Here is where AI search diverges most sharply from Google. Google delivers a list of links — the user decides which to visit. AI assistants synthesize information from multiple sources into a single, direct answer — the user may never visit any source at all.

    When an AI system generates a response, it is making decisions about:

    • Which sources to consult (determined by its retrieval system and trained knowledge)
    • Which content to paraphrase or quote (determined by relevance and clarity)
    • Whether to attribute the source (determined by the platform’s citation behavior)
    • How to present the synthesized answer (determined by the query intent)

    Being “found” by an AI assistant means your content was retrieved, understood, and judged useful enough to inform the answer. That process rewards different things than traditional ranking.


    Ranking vs Citation: The Core Distinction

    This is the conceptual shift that matters most for strategy.

    Ranking is about position. Your page competes with other pages for a slot in a list of results. Users see your title, your URL, and a snippet — and they decide whether to click.

    Citation is about being understood. Your content is evaluated for whether it can answer a specific question clearly and authoritatively. If it can, it becomes an input to the AI’s synthesized response. You may be named as a source, paraphrased without credit, or used as background context — depending on the platform and the nature of the query.

    The implication is significant: being cited requires being understood, not just indexed.

    A page can rank #1 on Google because it has excellent backlinks and keyword optimization — yet be ignored by AI systems because its content is vague, poorly structured, or buries the answer under excessive preamble.

    Conversely, a page that ranks on page two can be cited regularly by AI assistants because it directly answers a specific question with clear, structured, authoritative content.

    The Four Citation Scenarios

    Think of every page on your site as falling into one of four categories:

    Ranks on GoogleDoes Not Rank
    Cited by AIBest outcome — visible across both channelsAI-only visibility; brand presence without click traffic
    Not Cited by AIGoogle traffic only; missing AI channelInvisible — no meaningful visibility in either system

    The goal of a combined SEO and GEO strategy is to move as many important pages as possible into the top-left quadrant: pages that rank and get cited.

    What Drives Citation

    The factors most associated with AI citation differ meaningfully from traditional ranking signals:

    • Directness: Does the content answer the question in the first paragraph, or does it make the reader hunt for the answer?
    • Structural clarity: Are headings informative? Are lists and tables used to organize comparable information?
    • Specificity: Does the content provide concrete details, data, and examples — or stay at a vague, general level?
    • Completeness: Does the page thoroughly cover its topic, or does it skim the surface?
    • Authority signals: Is the source credible based on external mentions, author credentials, and consistency of expertise?
    • Freshness: For time-sensitive queries, when was the content last updated?

    Similarities and Differences: A Direct Comparison

    Despite their structural differences, Google SEO and AI SEO share more common ground than they diverge. Both reward the same foundational investments — the difference lies in emphasis and measurement.

    DimensionGoogle SEOAI SEO (GEO)
    Discovery methodCrawl → index → rankCrawl → retrieve at query time
    What the user seesRanked list of linksSynthesized answer with cited sources
    Success metricRanking position, organic trafficCitation frequency, answer inclusion
    Content signalsKeywords, backlinks, E-E-A-TClarity, structure, specificity, authority
    Technical needsFast, crawlable, mobile-friendlyFast, crawlable, server-rendered HTML
    Freshness weightHigh for news; lower for evergreenHigh for retrieval-based AI systems
    Structured dataEnhances rich resultsGives AI explicit machine-readable context
    Measurement toolsSearch Console, rank trackersAI querying, brand monitoring, referral traffic

    Where they fully overlap: both systems reward fast-loading pages, accessible HTML, genuine topical authority, accurate structured data, and well-written content that serves the user’s actual intent.

    Where they diverge: Google tolerates some structural ambiguity and rewards keyword strategy in ways AI systems do not. AI systems weight directness and structural clarity more heavily than keyword placement. And critically, AI systems cannot evaluate content they cannot access in plain HTML — a JavaScript-rendered page that Google eventually indexes may be completely invisible to AI crawlers.


    Why Both Matter — And Why You Should Not Choose

    The temptation, having understood the differences, is to declare one system more important than the other and concentrate resources there.

    Resist it.

    Google still dominates search traffic volume. For the vast majority of businesses, Google-driven organic traffic remains the largest single digital acquisition channel. Abandoning traditional SEO practices in favor of GEO alone would be a significant mistake.

    AI search is growing rapidly and influencing decisions. Even when users don’t click through from an AI answer, the brand mentions, recommendations, and citations that AI systems produce influence perception and downstream search behavior. Being absent from AI-generated answers is increasingly a competitive disadvantage.

    The investment is largely shared. A site that is technically sound (fast, server-rendered, crawlable), content-rich (thorough, structured, authoritative), and built with genuine topical depth will perform well in both systems. The marginal cost of adding GEO to a strong SEO program is far lower than building either from scratch.

    The compounding effect is real. A page that ranks well on Google and gets cited by AI systems earns visibility through two independent channels. Over time, AI citation can also drive the external mentions and backlinks that strengthen Google rankings — the two systems reinforce each other.

    The practical recommendation: treat GEO as additive optimization on top of a solid SEO foundation, not as a competing strategy.


    What This Means for Your Strategy Right Now

    Understanding the distinction between ranking and citation leads to three immediate strategic implications:

    1. Audit your content for citability, not just keyword coverage. Review your highest-traffic pages and ask: does this page answer a specific question directly, in the first paragraph, in clear and structured language? If not, it may rank on Google but fail to earn AI citations. Updating those pages for directness is one of the highest-leverage content investments available.

    2. Verify your technical accessibility for AI crawlers. Google will eventually render your JavaScript. GPTBot and PerplexityBot will not. If your content depends on client-side JavaScript to appear, you have a GEO problem regardless of your Google rankings. Confirm that your pages deliver full content in the server response — that single technical check can reveal a significant visibility gap.

    3. Expand your success metrics. If your team measures only rankings and organic traffic, you are missing the AI citation channel entirely. Begin querying ChatGPT Search, Perplexity, and Claude for your target topics on a regular basis. Note which sources they cite. Identify where your content should appear but doesn’t. That gap is your GEO opportunity.


    The New Rules of Online Discovery

    Search in 2026 operates through two parallel systems: Google’s ranking engine and AI’s citation engine. They share technical foundations, reward similar content quality, and serve the same users — but they measure success differently and respond to different optimization signals.

    Ranking is about competing for a position in a list. Citation is about being understood well enough to inform an answer.

    Both matter. Neither is sufficient alone.

    The businesses building visibility across both channels — by combining strong SEO fundamentals with deliberate GEO practices — are the ones establishing compounding advantages as AI search continues to grow.


    Next: What AI Crawlers Actually See When They Visit Your Website →

    ← Previous: The Future of SEO: How AI Search Is Changing Website Visibility in 2026

    This article is part of a 20-article series on SEO, GEO, and AI Visibility. View the complete series →
  • Google SEO vs AI SEO: Understanding the New Rules of Online Discovery

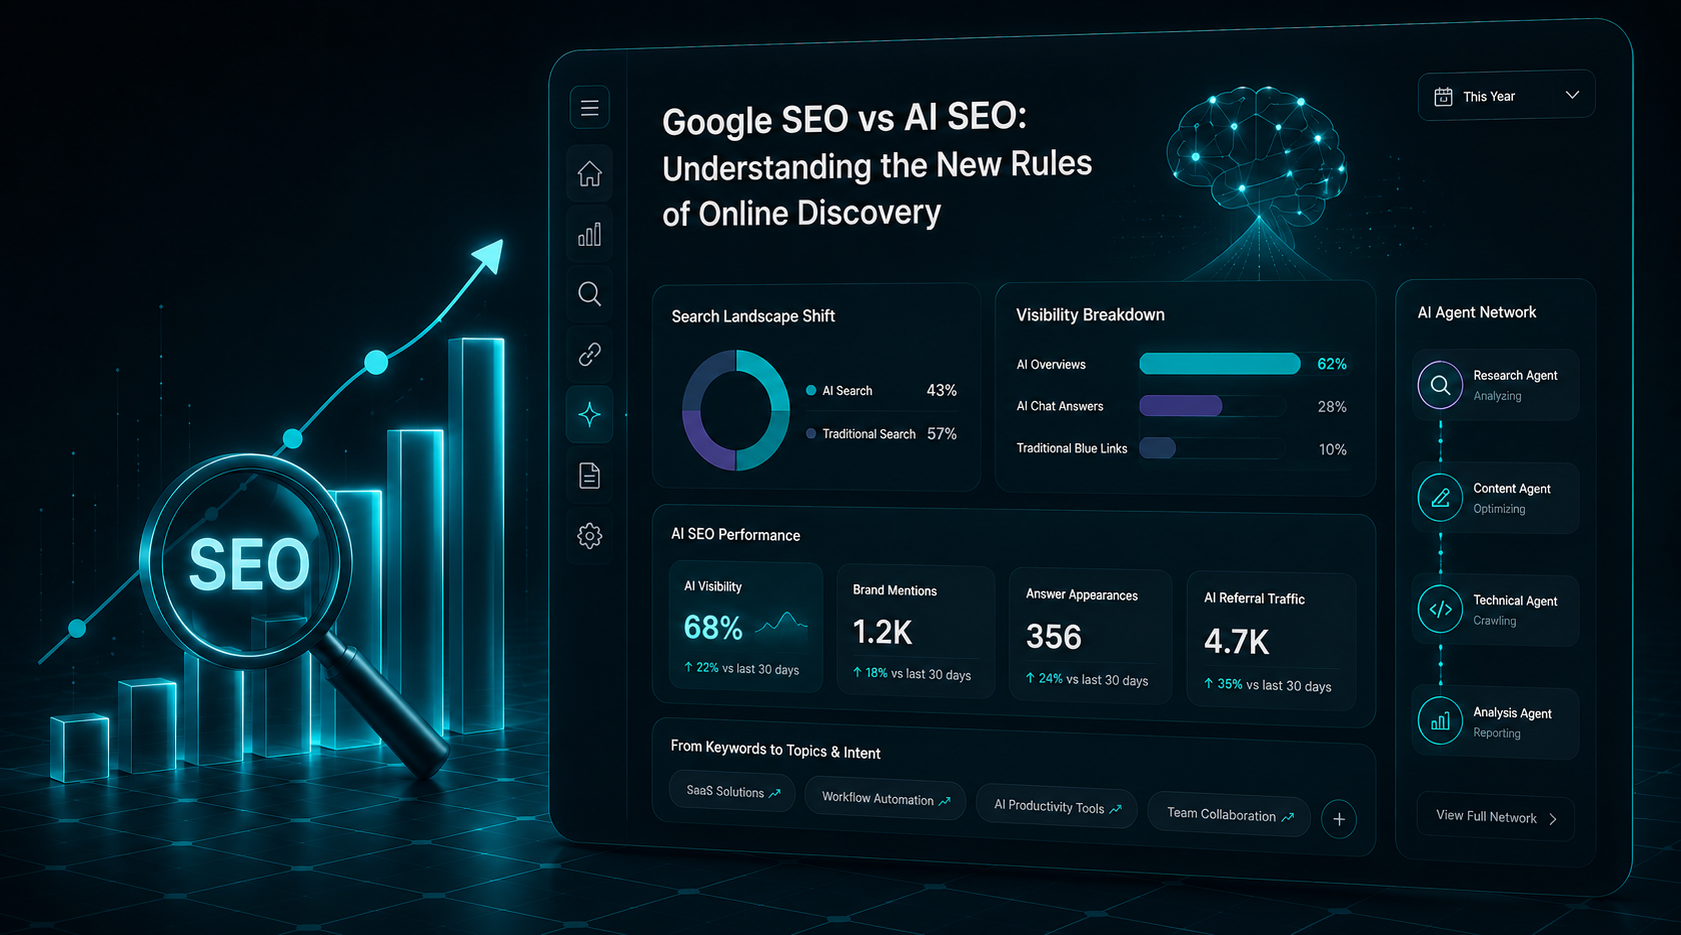
    Google SEO vs AI SEO: Understanding the New Rules of Online Discovery

    If you’ve been paying attention to the search landscape in 2026, you’ve probably started asking a version of the same question: Do I focus on Google, or do I focus on AI search?

    It’s the wrong question — but it’s an understandable one. The two systems look different, behave differently, and reward different things. Treating them as competing priorities, however, is a mistake that leads to underinvesting in both.

    The right question is: How do Google SEO and AI SEO differ, where do they overlap, and how do I build a strategy that serves both?

    This article answers all three. By the end, you’ll understand exactly how each system finds and evaluates content, what the shift from ranking to citation means in practice, and why the most effective digital strategies in 2026 treat AI SEO not as a replacement for traditional SEO but as a required layer on top of it.


    How Google Finds Content

    Google’s process for surfacing content has three distinct stages: crawling, indexing, and ranking. Understanding each stage clarifies what traditional SEO is actually optimizing for.

    Crawling

    Googlebot — Google’s automated web crawler — discovers pages by following links across the internet and reading XML sitemaps that websites submit. When Googlebot visits a page, it downloads the HTML (and, with a delay, attempts to render any JavaScript) and stores that raw content for processing.

    The practical implication: pages that aren’t linked to, aren’t in sitemaps, or are blocked by robots.txt rules simply don’t enter Google’s awareness. Crawlability is the prerequisite for everything else.

    Indexing

    Once crawled, Google’s systems analyze the page’s content — text, structure, metadata, images, links — and store it in Google’s index, associating it with the topics and queries it appears to address.

    Not every crawled page gets indexed. Pages Google judges as low-quality, duplicate, or irrelevant may be crawled but never stored. The indexed page is what competes in search results.

    Ranking

    When a user submits a query, Google’s ranking algorithms evaluate every indexed page relevant to that query and assign positions based on hundreds of signals. The most significant include:

    • PageRank and backlinks: How many credible external sites link to this page, and what is the authority of those sites?
    • E-E-A-T: Does the content demonstrate Experience, Expertise, Authoritativeness, and Trustworthiness?
    • Relevance: How closely does the page’s content match the user’s query intent?
    • Core Web Vitals: Does the page load quickly, remain visually stable, and respond promptly to interaction?
    • Freshness: For time-sensitive queries, how recently was the content published or updated?

    The outcome of this process is a ranked list of links. Users see results, evaluate them, and choose where to click. Traffic flows from Google to your page.

    What Google rewards, in summary: relevance to the query, authority signals from backlinks and E-E-A-T, technical quality, and freshness where applicable.


    How AI Assistants Find Information

    AI-powered search systems — ChatGPT Search, Perplexity AI, Google AI Overviews, Microsoft Copilot, Claude — work through a fundamentally different process. There are two mechanisms at play, and most AI search products use a combination of both.

    Trained Knowledge

    Large language models (LLMs) are trained on enormous datasets of text gathered from across the internet, books, academic papers, and other sources. This training process encodes a vast amount of factual knowledge directly into the model’s parameters.

    When a user asks a question, the model can answer from this trained knowledge without consulting any external source. The information it has access to, however, is frozen at its training cutoff date — it does not update in real time.

    Live Retrieval

    To address the freshness problem and to ground answers in current sources, most AI search products layer a retrieval system on top of trained knowledge. At query time, a crawler fetches relevant pages from the web, extracts their content, and passes that content to the language model as context for generating the answer.

    This is how GPTBot (OpenAI), PerplexityBot, ClaudeBot (Anthropic), and Bingbot operate in the context of AI search products. They are not indexing pages for later ranking — they are fetching pages at the moment a user asks a question, to inform the answer being generated right now.

    The Critical Difference: Synthesis, Not Links

    Here is where AI search diverges most sharply from Google. Google delivers a list of links — the user decides which to visit. AI assistants synthesize information from multiple sources into a single, direct answer — the user may never visit any source at all.

    When an AI system generates a response, it is making decisions about:

    • Which sources to consult (determined by its retrieval system and trained knowledge)
    • Which content to paraphrase or quote (determined by relevance and clarity)
    • Whether to attribute the source (determined by the platform’s citation behavior)
    • How to present the synthesized answer (determined by the query intent)

    Being “found” by an AI assistant means your content was retrieved, understood, and judged useful enough to inform the answer. That process rewards different things than traditional ranking.


    Ranking vs Citation: The Core Distinction

    This is the conceptual shift that matters most for strategy.

    Ranking is about position. Your page competes with other pages for a slot in a list of results. Users see your title, your URL, and a snippet — and they decide whether to click.

    Citation is about being understood. Your content is evaluated for whether it can answer a specific question clearly and authoritatively. If it can, it becomes an input to the AI’s synthesized response. You may be named as a source, paraphrased without credit, or used as background context — depending on the platform and the nature of the query.

    The implication is significant: being cited requires being understood, not just indexed.

    A page can rank #1 on Google because it has excellent backlinks and keyword optimization — yet be ignored by AI systems because its content is vague, poorly structured, or buries the answer under excessive preamble.

    Conversely, a page that ranks on page two can be cited regularly by AI assistants because it directly answers a specific question with clear, structured, authoritative content.

    The Four Citation Scenarios

    Think of every page on your site as falling into one of four categories:

    Ranks on GoogleDoes Not Rank
    Cited by AIBest position — maximum visibility across all channelsGrowing channel — AI citations drive some traffic and brand visibility even without Google ranking
    Not Cited by AITraditional SEO success — traffic from Google onlyInvisible — neither channel delivers meaningful visibility

    The goal of a combined SEO and GEO strategy is to move as many important pages as possible into the top-left quadrant: pages that rank and get cited.

    What Drives Citation

    The factors most associated with AI citation differ meaningfully from traditional ranking signals:

    • Directness: Does the content answer the question in the first paragraph, or does it make the reader hunt for the answer?
    • Structural clarity: Are headings informative? Are lists and tables used to organize comparable information?
    • Specificity: Does the content provide concrete details, data, and examples — or stay at a vague, general level?
    • Completeness: Does the page thoroughly cover its topic, or does it skim the surface?
    • Authority signals: Is the source credible based on external mentions, author credentials, and consistency of expertise?
    • Freshness: For time-sensitive queries, when was the content last updated?

    Similarities and Differences: A Direct Comparison

    Despite their structural differences, Google SEO and AI SEO share more common ground than they diverge. Both reward the same foundational investments — the difference lies in emphasis and measurement.

    DimensionGoogle SEOAI SEO (GEO)
    How content is discoveredCrawl → index → rankCrawl → retrieve at query time, or draw from trained knowledge
    What the user seesA list of ranked linksA synthesized answer, sometimes with cited sources
    Success metricRanking position, organic trafficCitation frequency, answer inclusion, brand mention
    Primary content signalsKeywords, backlinks, E-E-A-TClarity, structure, specificity, authority
    Technical requirementsFast, crawlable, mobile-friendly, HTTPSFast, crawlable, server-rendered HTML, semantic markup
    Freshness weightHigh for news/time-sensitive; lower for evergreenHigh for retrieval-based AI (Perplexity); lower for model-trained knowledge
    Structured data valueEnhances rich resultsProvides explicit machine-readable context for AI systems
    Measurement toolsGoogle Search Console, rank trackersManual AI querying, brand monitoring, referral traffic

    Where they fully overlap: both systems reward fast-loading pages, accessible HTML, genuine topical authority, accurate structured data, and well-written content that serves the user’s actual intent.

    Where they diverge: Google tolerates some structural ambiguity and rewards keyword strategy in ways AI systems do not. AI systems weight directness and structural clarity more heavily than keyword placement. And critically, AI systems cannot evaluate content they cannot access in plain HTML — a JavaScript-rendered page that Google eventually indexes may be completely invisible to AI crawlers.


    Why Both Matter — And Why You Should Not Choose

    The temptation, having understood the differences, is to declare one system more important than the other and concentrate resources there.

    Resist it.

    Google still dominates search traffic volume. For the vast majority of businesses, Google-driven organic traffic remains the largest single digital acquisition channel. Abandoning traditional SEO practices in favor of GEO alone would be a significant mistake.

    AI search is growing rapidly and influencing decisions. Even when users don’t click through from an AI answer, the brand mentions, recommendations, and citations that AI systems produce influence perception and downstream search behavior. Being absent from AI-generated answers is increasingly a competitive disadvantage.

    The investment is largely shared. A site that is technically sound (fast, server-rendered, crawlable), content-rich (thorough, structured, authoritative), and built with genuine topical depth will perform well in both systems. The marginal cost of adding GEO to a strong SEO program is far lower than building either from scratch.

    The compounding effect is real. A page that ranks well on Google and gets cited by AI systems earns visibility through two independent channels. Over time, AI citation can also drive the external mentions and backlinks that strengthen Google rankings — the two systems reinforce each other.

    The practical recommendation: treat GEO as additive optimization on top of a solid SEO foundation, not as a competing strategy.


    What This Means for Your Strategy Right Now

    Understanding the distinction between ranking and citation leads to three immediate strategic implications:

    1. Audit your content for citability, not just keyword coverage. Review your highest-traffic pages and ask: does this page answer a specific question directly, in the first paragraph, in clear and structured language? If not, it may rank on Google but fail to earn AI citations. Updating those pages for directness is one of the highest-leverage content investments available.

    2. Verify your technical accessibility for AI crawlers. Google will eventually render your JavaScript. GPTBot and PerplexityBot will not. If your content depends on client-side JavaScript to appear, you have a GEO problem regardless of your Google rankings. Confirm that your pages deliver full content in the server response — that single technical check can reveal a significant visibility gap.

    3. Expand your success metrics. If your team measures only rankings and organic traffic, you are missing the AI citation channel entirely. Begin querying ChatGPT Search, Perplexity, and Claude for your target topics on a regular basis. Note which sources they cite. Identify where your content should appear but doesn’t. That gap is your GEO opportunity.


    The New Rules of Online Discovery

    Search in 2026 operates through two parallel systems: Google’s ranking engine and AI’s citation engine. They share technical foundations, reward similar content quality, and serve the same users — but they measure success differently and respond to different optimization signals.

    Ranking is about competing for a position in a list. Citation is about being understood well enough to inform an answer.

    Both matter. Neither is sufficient alone.

    The businesses building visibility across both channels — by combining strong SEO fundamentals with deliberate GEO practices — are the ones establishing compounding advantages as AI search continues to grow.


    Next: What AI Crawlers Actually See When They Visit Your Website →

    ← Previous: The Future of SEO: How AI Search Is Changing Website Visibility in 2026

    This article is part of a 20-article series on SEO, GEO, and AI Visibility. View the complete series →
  • The Future of SEO: How AI Search Is Changing Website Visibility in 2026

    The Future of SEO: How AI Search Is Changing Website Visibility in 2026

    For more than two decades, SEO meant one thing: rank higher on Google. Businesses invested in keywords, backlinks, and technical optimization — all in pursuit of a better position on search engine results pages.

    That goal has not disappeared. But in 2026, it is no longer enough.

    Artificial intelligence is reshaping how people find information online. Instead of scanning a list of links and clicking through to websites, users are increasingly receiving direct, synthesized answers from AI-powered tools. The question is no longer only where does my page rank? It is also will AI systems trust my content enough to cite it?

    This article explains what changed, why it matters, and what your business must do to stay visible in an AI-first search environment.


    What Changed in Search

    Traditional search presents users with a ranked list of links. A user enters a query, reviews the results, and chooses which website to visit. Traffic flows from the search engine to your page.

    AI-powered search works differently. Instead of serving links, AI systems analyze content from multiple sources and generate a direct answer. The user gets a response — sometimes without visiting any website at all.

    This is not a future trend. It is already the default experience on tools millions of people use daily: Google AI Overviews, ChatGPT Search, Perplexity AI, and Microsoft Copilot.

    The practical consequence is significant. A page that ranks in position one can still lose traffic if an AI summary answers the user’s question before they scroll. Meanwhile, a page that ranks in position eight may be cited by AI systems because it provides the clearest, most authoritative answer.

    Website visibility is no longer defined by ranking position alone. It is defined by whether AI systems judge your content trustworthy enough to include in their answers.


    The Rise of AI-Powered Discovery

    Consider how search behavior is changing. A user researching software in 2022 might search:

    “Best accounting software for small businesses”

    The same user in 2026 is more likely to ask:

    “What accounting software is best for a service business with fewer than 20 employees that needs invoicing and payroll in one tool?”

    AI systems can answer this directly — synthesizing information from product pages, reviews, comparison sites, and expert sources — without the user visiting a single website.

    This shift has several implications:

    • Keyword targeting is insufficient on its own. Users phrase queries conversationally, and AI systems interpret intent rather than match exact terms.
    • Content must answer real questions, not approximate them. Vague, keyword-stuffed content is ignored by AI systems in favor of direct, expert answers.
    • Brand authority is now a visibility signal. AI systems are more likely to cite sources they have encountered repeatedly across credible contexts — mentions, publications, reviews, and citations all contribute.

    The businesses that consistently provide clear, accurate, expert-level answers to specific questions are the ones AI systems will cite. That is the new definition of organic visibility.


    Why Rankings Alone Are No Longer Enough

    Ranking on page one of Google remains valuable. It should remain part of your strategy. But it is no longer the complete picture of online visibility.

    Here is the new reality:

    A high-ranking page can lose traffic if an AI summary answers the user’s query above the organic results. Zero-click searches — where users get what they need without clicking — are growing significantly as AI summaries expand.

    A lower-ranking page can gain citation visibility if it provides the most specific, well-structured answer to a question. AI systems do not rank-order their sources the way Google does. They select for relevance, clarity, and authority.

    This creates both a risk and an opportunity:

    Traditional SEO RealityNew AI Search Reality
    Position 1 guarantees maximum visibilityPosition 1 does not guarantee being cited
    Traffic comes from clicks on linksValue also comes from being cited in AI answers
    Keyword density signals relevanceContent clarity and specificity signal relevance
    Backlinks build authorityBacklinks + citations + mentions build authority
    Success measured in rankingsSuccess measured in rankings and citation frequency

    Businesses focused exclusively on traditional ranking metrics are increasingly blind to a growing share of search activity.


    Understanding GEO (Generative Engine Optimization)

    Generative Engine Optimization (GEO) is the practice of optimizing content so AI-powered search engines and answer engines can discover, understand, and cite it.

    GEO does not replace SEO. It extends it. The same content quality and technical accessibility that help Google rank your pages also help AI systems understand and cite them. But GEO adds a layer of specific practices that traditional SEO does not address.

    Creating Authoritative Content

    AI systems favor content that demonstrates expertise, depth, and accuracy. A thorough, well-researched 1,500-word answer to a specific question outperforms five generic 300-word posts on loosely related topics. Depth and specificity are the primary currency of GEO.

    Structuring Information Clearly

    How content is organized determines whether AI systems can extract meaning from it. Clear headings that function as questions, concise opening sentences that answer those questions directly, tables for comparisons, and lists for processes — these structural choices directly influence whether your content gets cited.

    AI systems parse HTML sequentially. A well-structured page with logical heading hierarchies (H1 → H2 → H3) and semantic markup gives AI systems an accurate map of your content.

    Building Topical Authority

    Publishing one excellent piece of content is valuable. Publishing comprehensive, interconnected content across an entire subject area is far more powerful. AI systems recognize topical authority — when a domain consistently provides high-quality information on a subject, it becomes a preferred source.

    This is why content clusters (a pillar article supported by deep supporting articles, like this series) are one of the most effective GEO strategies available.

    Maintaining Accuracy and Freshness

    Outdated or inaccurate content damages credibility with AI systems. Platforms like Perplexity AI weight freshness heavily for time-sensitive queries. Regular content audits and updates signal that your site is a reliable, current source.

    Strengthening Brand Signals

    AI models are trained on large bodies of text from across the internet. Brands mentioned frequently and positively across credible sources — news articles, industry publications, reviews, and expert citations — carry stronger authority signals into AI systems’ training data.

    Digital PR, guest contributions, original research, and thought leadership that earns external citations all build the brand signal that makes AI systems more likely to trust and reference your content.


    What Businesses Must Do Next

    The shift to AI-powered discovery is not approaching — it is already underway. Businesses that adapt their strategy now will compound their advantage as AI search continues to grow.

    The immediate priorities:

    1. Audit your crawlability. Ensure AI crawlers (GPTBot, PerplexityBot, ClaudeBot) can access your content. Check your robots.txt file. Verify your pages deliver complete HTML content in the server response — not via JavaScript that AI crawlers cannot execute.
    2. Shift content strategy toward direct answers. Identify the specific questions your audience is asking. Write content that answers those questions in the first paragraph, then elaborates. Answer-first writing is the single most effective content change you can make for GEO.
    3. Implement structured data. Schema markup (Article, FAQPage, HowTo, Organization) gives AI systems explicit, machine-readable context about your content. This is one of the highest-leverage technical GEO improvements available.
    4. Build topical depth, not just breadth. A content cluster that comprehensively covers a subject area will outperform a scattered collection of one-off posts in AI citation systems.
    5. Measure beyond rankings. Begin monitoring how your brand appears in AI-generated answers. Query ChatGPT, Perplexity, and Claude for your target topics. Track what they say about you and your industry — and whether your content is being cited.
    6. Combine SEO and GEO. Both disciplines share the same foundation: technically accessible, fast, high-quality content. A strong SEO program and a GEO strategy are not competing priorities — they are the same investment applied to two distribution channels.

    The New Measure of Online Visibility

    The goal of digital marketing has always been to reach the right audience at the moment they need what you offer. For two decades, that meant ranking on Google. In 2026, it also means being the source that AI systems trust enough to cite when generating answers.

    The businesses positioned to win are those that prioritize authority, clarity, and technical accessibility — not as separate strategies, but as a unified approach to content that serves both human readers and AI systems equally well.

    Rankings still matter. They are not the whole story anymore.


    Next: Google SEO vs AI SEO: Understanding the New Rules of Online Discovery →

    This article is part of a 20-article content cluster on SEO, GEO, and AI Visibility. View the complete series →
  • Why AI Cites Your Competitors Instead of You

    Why AI Cites Your Competitors Instead of You

    The Foundational Misdiagnosis

    Answer engine optimization is not “SEO but for ChatGPT.” The two disciplines serve different retrieval mechanisms.

    The confusion starts with a surface-level similarity: both disciplines are about visibility. But the mechanism is completely different, and the difference matters operationally. Whether you call it generative engine optimization or answer engine optimization, the target is the same — earning citations inside AI-generated responses rather than positions in a ranked list of blue links.

    Traditional SEO Answer Engine Optimization (AEO)
    Earns a position in a ranked list of links. The user decides whether to click. You are competing for attention in a results page the user actively scans. Click-through rates at position #1: around 28%. At position #3: closer to 11%. Earns a citation inside a synthesized answer. The AI has already decided what the answer is — your brand either appears in it or does not. There is no position #3. Visibility is effectively binary — you’re cited or you’re absent.

    A strong Google ranking remains the primary driver of AI citation visibility — the majority of cited sources in AI responses draw from top organic results. However, ranking alone does not guarantee that an AI system will extract and cite a specific page’s content; the structure and clarity of the page content also influence whether it gets referenced.

    The space is young enough that thoughtful execution matters more than speed. The core dynamic is straightforward: your well-ranked owned content is the primary driver of AI citation visibility (the RAG pipeline draws predominantly from indexed search results), while third-party coverage on external platforms can expand the range of contexts in which your brand appears. Neither replaces the other — they are complementary.


    The Architecture of AI Visibility

    Three non-negotiable layers. Missing one reduces the impact of the others.

    Pillar I — Content Layer: Semantic Density

    LLMs are trained to retrieve self-contained, definitionally rich answers. A page that raises a question and then defers to another source for context is, from the retrieval model’s perspective, incomplete — and incompleteness is penalized by lower confidence scoring.

    The Princeton/Georgia Tech/Allen Institute peer-reviewed study (KDD 2024, 10,000 queries across 25 domains) tested on-page content mutations — adding statistics, citations, and fluency improvements to existing pages — in a controlled setting. It found measurable improvements:

    – Including statistics: roughly +32% visibility lift

    – Adding citations: roughly +30%

    – Optimizing fluency: roughly +28%

    These numbers reflect the controlled study conditions; real-world results vary based on competition, domain authority, and implementation quality. The study’s scope is limited to on-page content changes and does not address back-end engineering like MCP servers or RAG pipelines.

    The standard:

    – Every page must answer the question it raises without requiring AI to cross-reference external sources for context. Run this filter: could an LLM extract a clean, attributable answer from this page alone?

    – Articles with structured data — hierarchical headings, comparison tables, numbered steps — are 28–40% more likely to be cited by large language models.

    – Content freshness matters: AI systems tend to factor recency into retrieval decisions. A visible “last updated” date and current statistics help signal relevance.

    Pillar II — Brand Layer: Entity Authority

    LLMs reason in entities — brands, products, authors, concepts — not keyword frequencies. Your brand functions as a node in a knowledge graph, and its weight in that graph influences whether it surfaces in retrieval. A 2026 industry snapshot found that 26% of brands had zero mentions in AI Overviews, suggesting gaps in how those brands present themselves as recognizable entities.

    The standard:

    – Schema markup is table stakes. Content with proper schema implementation shows 30–40% higher visibility in AI-generated answers (Dataslayer, 2026).

    – Consistent NAP data and presence in authoritative industry databases are not optional extras — they are the entry ticket to AI retrieval pools.

    – E-E-A-T signals now directly influence which domains generative models choose as sources. Author entities with verifiable credentials outperform anonymous content.

    – When evaluating an approach, verify that entity authority work is part of the plan. A content rewrite without entity grounding produces limited results.

    Pillar III — Trust Layer: Citation Architecture

    Retrieval models assign confidence scores partly based on the web graph. A page that stands in isolation reads as low-confidence. You need to be a central node, not a leaf node — referenced by others, referencing primary sources, and building internal citation chains that demonstrate the authority of your proprietary data.

    According to Semrush’s AI Visibility Index, 40–60% of cited sources in AI responses rotate month over month. Maintaining citations is an active, continuous process — not a one-time optimization.

    The standard:

    – Build explicit citation chains: reference primary data, link to foundational documents, cite your own proprietary research with transparent methodology.

    – Distributing content across multiple publications broadens the contexts in which your brand may be cited.

    – Monitor continuously. Brands with citation monitoring detect drift faster than those without it.


    Where Most Strategies Fail

    Answer engine optimization is an infrastructure challenge, not just a content one.

    True AI visibility requires moving beyond on-page optimization into how your data is structured for machine retrieval. Content rewrites alone produce limited results if the underlying data architecture does not support AI retrieval.

    The MCP Shift — What Your Engineering Team Needs to Understand

    >

    Model Context Protocol (MCP), introduced as an open standard, allows AI agents to connect directly to external data sources. Its primary use case today is internal enterprise AI ecosystems — custom chatbots, support agents, and private AI tools that query your own knowledge base. Public consumer AI engines (ChatGPT, Perplexity, Google Gemini) do not dynamically crawl private MCP endpoints when answering general user queries. They continue to rely on standard web crawlers (GPTBot, Bingbot) and indexed web content. MCP is not a shortcut to bypass search engine ranking — it is a complementary tool for closed-ecosystem integrations.

    RAG pipelines, Knowledge Graph integration, and MCP server architecture bridge marketing and engineering concerns. Organizations with cross-functional teams — a content strategist, a technical SEO architect, and an engineer familiar with retrieval systems — are often better positioned to execute across all three layers.


    Applied ROI — Three Enterprise Cases

    What measurable returns from these approaches look like in practice.

    Business Type Core Problem Intervention Measured Outcome
    B2B SaaS — High CAC, crowded market Buyers using Perplexity for vendor research; brand absent from AI-generated comparisons Full entity architecture rebuild + technical docs structured for MCP and RAG retrieval +340% brand citations in Perplexity (90 days); +28% organic traffic from high-intent AI queries; 60+ new featured snippets (8 weeks)
    Enterprise E-commerce — Product discovery High-margin products absent from generative AI shopping recommendations due to flat product descriptions Semantic density overhaul on category pages + aggressive product schema deployment Direct reduction in dependency on bottom-funnel PPC; AI-referred visitors convert at 4× higher rate than unassisted organic
    Enterprise Support — Knowledge management High Tier-1 ticket volume because AI assistants cannot extract answers from legacy help center Restructured support docs for maximum semantic density with LLM-parseable step-by-step formatting Significant ticket deflection — users ask their AI tool, receive clean accurate answers sourced from the company

    The pattern across all three: the financial return materializes at the intersection of content quality, entity definition, and retrieval architecture. Any single pillar in isolation produces marginal results. The multiplier effect requires all three working simultaneously.


    Priority Sequence: Where to Start

    A suggested ordering based on common industry patterns, not a rigid playbook.

    The sequence below reflects a logical dependency chain — each step builds on the one before it. You may find your organization already has some pieces in place, in which case the ordering will differ.

    Priority 1: Audit & Entity Establishment

    Define your brand as an entity the web can agree on.

    Map your current Knowledge Graph footprint. Audit structured data gaps using Google’s Rich Results Test. Establish or update your author entities with verifiable credentials. Ensure consistent representation across major industry databases. Fix NAP inconsistencies. Document what AI tools currently say about your brand — this is your baseline, and you cannot optimize what you have not measured.

    Priority 2: Semantic Density Overhaul

    Rebuild your highest-value content for LLM retrieval standards.

    Identify your ten highest-traffic legacy pages. Rewrite them to achieve semantic density: definitional clarity, self-contained context, explicit citations, original statistics, and structured formatting (comparison tables, numbered steps, clear hierarchical headings). Add a “What changed in 2026” section to perennial articles — freshness is a ranking signal for AI systems, not just humans. The target: could an LLM extract a complete, attributable answer from this page alone, without cross-referencing anything else? If not, the page has a density problem.

    Priority 3: Pipeline Architecture

    Structure proprietary data for internal enterprise AI tools.

    Engage your engineering team. Identify your highest-value proprietary data assets: product catalogs, technical documentation, pricing matrices, support knowledge bases. Structure these for internal RAG pipeline access and MCP server implementation. This is primarily relevant for closed-ecosystem AI tools — custom chatbots, internal support agents, and private AI assistants that query your own data. For public search visibility, the two prior priorities (entity authority and semantic content density) remain the primary levers.


    On Compounding Effects

    Citation authority can accumulate similarly to how domain authority did in traditional SEO.

    In 2012, brands that invested early in domain authority built positions that later entrants found difficult to replicate. A similar dynamic may apply to AI citation authority, though the landscape is too new for definitive long-term conclusions.

    AI search landscapes evolve through discrete algorithm updates rather than gradual monthly shifts. Sustained investment in content quality and entity structure is more reliable than attempting to race an arbitrary timeline.

    There is also a conversion asymmetry that changes the ROI calculation entirely. AI-referred visitors arrive pre-qualified: they have already received a recommendation from a trusted interface, they arrive with context and intent built in, and they spend nearly twice as long on site as Google referrals (15 minutes vs. 8 minutes, per Seer Interactive). This is structurally different from clicking position three on a search result page. The visitor who arrives from a ChatGPT recommendation is closer to a warm referral than a cold organic click — and your content strategy, landing pages, and conversion architecture should reflect that distinction.


    If there is a single takeaway, it is this: your traditional SEO foundation still matters — 99% of AI Overview citations come from the organic top 10, and 87% of ChatGPT citations map to top Bing results. Ranking well on standard search engines is still the entry ticket. What AEO adds is the layer that determines whether that ranking translates into an AI citation — through entity clarity, semantic density, and a strategic mix of owned and third-party content.

    Build the entity. Earn the citation. Keep your foundations solid. Brands that invest in this sequence create a citation advantage that compounds over time.


    Sources & Verification: Key sources referenced in this article include: OpenAI (ChatGPT user data, February 2026); Gartner VP Analyst Alan Antin (search volume projections, 2024); Princeton/Georgia Tech/Allen Institute for AI/IIT Delhi — “GEO: Generative Engine Optimization,” KDD 2024 peer-reviewed study; Seer Interactive conversion rate analysis (June 2025); Conductor AEO/GEO Benchmarks Report (January 2026, 13,770 domains, 10 industries); Semrush AI Visibility Index (2026); HubSpot 2026 State of Marketing Report. Statistical claims reflect findings as reported under specific study conditions; enterprise results vary by vertical, existing authority, and implementation fidelity.

  • The Ultimate Guide to Incremental Static Regeneration (ISR) in Next.js

    The Ultimate Guide to Incremental Static Regeneration (ISR) in Next.js

    Most teams running large content sites face the same trade-off: full static generation gives you the fastest possible page loads, but rebuilding thousands of pages every time a single post changes becomes slow and expensive. Pure server-side rendering solves the freshness problem but adds latency to every single request. Incremental Static Regeneration (ISR) was built specifically to remove that trade-off, and it’s one of the most practical features in the Next.js rendering toolkit.

    This guide covers what ISR actually does, how the caching model works under the hood, how to implement it in both the Pages Router and the App Router, and the pitfalls that trip up most teams the first time they use it.

    What Is ISR?

    ISR is a hybrid rendering strategy that sits between Static Site Generation (SSG) and Server-Side Rendering (SSR). Pages are generated as static HTML at build time, just like SSG, but instead of staying frozen until the next full deployment, individual pages can be regenerated in the background after a set time interval or on demand, without rebuilding the rest of the site.

    In practice, this means a 10,000-page blog or e-commerce catalog can ship in seconds, while individual pages quietly refresh themselves as their content changes.

    How ISR Works: Stale-While-Revalidate

    ISR follows a stale-while-revalidate model:

    1. The first request for a page is served from the static cache, generated either at build time or on first visit.
    2. Once the page’s revalidate window has passed, the next visitor still receives the cached (now “stale”) version instantly — there’s no waiting on a rebuild.
    3. In the background, Next.js regenerates that page using fresh data.
    4. Once regeneration finishes, the cache is updated, and all subsequent requests receive the new version.

    The key benefit: no visitor ever waits on a regeneration. They either get a fully fresh page or a slightly stale one, never a loading spinner.

    Implementing ISR

    ISR is configured slightly differently depending on which router your project uses.

    Pages Router

    If you’re on the older Pages Router, ISR is configured with the revalidate property inside getStaticProps:

    export async function getStaticProps() {
      const res = await fetch('https://your-api.com/posts');
      const posts = await res.json();
    
      return {
        props: { posts },
        revalidate: 60, // regenerate at most once every 60 seconds
      };
    }
    

    revalidate: 60 doesn’t mean the page rebuilds every 60 seconds on a timer — it means the page becomes eligible for regeneration on the next request that arrives after that window closes.

    App Router

    The App Router (the current standard since Next.js 13+) handles this in one of two ways.

    Route segment config, applied to an entire route:

    // app/blog/[slug]/page.tsx
    export const revalidate = 60;
    
    export default async function Post({ params }) {
      const res = await fetch(`https://your-api.com/posts/${params.slug}`);
      const post = await res.json();
      return <Article post={post} />;
    }
    

    Per-fetch revalidation, applied to a specific data request:

    const res = await fetch('https://your-api.com/posts', {
      next: { revalidate: 60 },
    });
    

    One detail worth knowing: in recent Next.js versions, fetch calls are uncached by default unless you explicitly opt in with next: { revalidate } or cache: 'force-cache'. If your pages aren’t caching the way you expect, this is usually why.

    On-Demand Revalidation

    Time-based revalidation works well for content that changes on a predictable schedule, but it’s not ideal when you need a page to update the instant content changes — for example, the moment an editor publishes a post in a headless WordPress backend. For that, Next.js supports on-demand revalidation via revalidatePath and revalidateTag, typically called from a Route Handler triggered by a CMS webhook:

    // app/api/revalidate/route.ts
    import { revalidatePath } from 'next/cache';
    
    export async function POST(request) {
      const { path } = await request.json();
      revalidatePath(path);
      return Response.json({ revalidated: true });
    }
    

    For a headless WordPress + Next.js stack — the kind of setup used for fast content management paired with a high-performance frontend — wiring a publish webhook to this endpoint means content goes live within seconds, with none of the staleness window that pure time-based ISR introduces.

    ISR vs. SSG vs. SSR vs. CSR

    Strategy Build cost Freshness First-byte speed Best for
    SSG Full rebuild per change Stale until rebuild Fastest Pages that rarely change
    ISR One-time build, incremental updates Near-fresh, configurable Fastest (cached) Large sites with periodic content changes
    SSR None (runs per request) Always fresh Slower (server work per request) Highly dynamic, user-specific content
    CSR None Fresh after JS loads Slow initial render Authenticated dashboards, apps

    Common Pitfalls

    A few mistakes account for most ISR problems in production.

    Setting revalidate too low (a few seconds) on high-traffic pages can effectively turn ISR into SSR, since pages regenerate almost continuously and lose most of the performance benefit.

    ISR requires a Node.js server runtime (such as next start, or hosting on a platform that supports it) — it does not work with a fully static export (output: 'export'), since there’s no server present to handle regeneration requests.

    For dynamic routes generated after build time, the fallback behavior in generateStaticParams (App Router) or getStaticPaths (Pages Router) determines whether new pages are blocked-and-rendered on first request or shown as a loading state — getting this wrong is a common source of confusing first-visit behavior on new content.

    Why This Matters For Your Business

    This isn’t just a detail for developers — it affects how much your website costs to run, how fast it loads for customers, and whether it shows up properly in Google and AI search results.

    Online stores and product catalogs

    Prices, stock levels, and seasonal listings change constantly. With the old approach, updating even one product often meant rebuilding the entire site — slow and expensive once you have thousands of products. This approach updates each product page on its own, so a single price change doesn’t touch anything else. Connected to your inventory system, a stock update can show up on the live site within seconds instead of waiting for the next full site update.

    Blogs, news sites, and content-heavy businesses

    New articles go live instantly without taking the whole site down to rebuild it, while older pages that rarely change keep loading instantly at almost no extra cost. There’s also something many business owners don’t realize: if a site relies too heavily on behind-the-scenes code to display its content, search engines and AI tools like ChatGPT or Google’s AI search may not actually see that content at all. Set up correctly, every visitor — human or search engine — sees the full page right away.

    Marketing pages and lead generation

    Pages built to convert visitors into customers — pricing pages, landing pages, sign-up forms — need to load instantly. Even a one-second delay can measurably hurt how many visitors turn into leads or customers. This approach gives those pages instant load speed, while still letting your marketing team update pricing, offers, or testimonials without waiting on a developer to push a full site update.

    If you’re not sure whether your website is actually set up to support your search rankings and sales goals — rather than just being convenient to build — that’s worth a second look.

    Frequently Asked Questions

    What’s the actual difference between ISR and SSR?

    SSR renders a page from scratch on every single request. ISR serves a cached static page and only regenerates in the background, after a set interval has passed — most visitors never trigger a server render at all.

    Does ISR work with a fully static export?

    No. output: 'export' produces a static site with no server, so there’s nothing to handle background regeneration. ISR needs a running Node.js server or a hosting platform built to support it.

    How do I update a page immediately instead of waiting for the revalidate timer?

    Use on-demand revalidation with revalidatePath or revalidateTag, typically triggered by a webhook from your CMS the moment content is published or edited.

    Can a visitor ever see a broken or half-rendered page during regeneration?

    No. The stale-while-revalidate model always serves either the previous complete version or the new complete version — regeneration happens entirely in the background.

    Does serving a stale page temporarily hurt SEO?

    Not meaningfully. Crawlers see the same fully-rendered static HTML a user would, and the staleness window is typically measured in seconds to minutes, not something that affects indexing or ranking.

    Key Takeaways

    ISR gives you the page-load speed of static generation without forcing a full rebuild every time content changes. Time-based revalidation works well for predictable content; on-demand revalidation is the right call when freshness needs to be near-instant, such as a CMS publish event. The tradeoffs to watch are runtime requirements (no static export), fallback behavior on new dynamic routes, and avoiding revalidate windows so short they erase the performance benefit entirely.

    Need Help Making Sure Your Website Works For Your Business, Not Just Your Developers?

    Every website is different, and the right setup depends on how big your site is, how often things change, and where your traffic comes from. If you’re not sure whether your current website is helping or hurting your search rankings and sales, get in touch through ahsanweb.com for a straightforward review.

    Related Reading

    Conclusion

    ISR isn’t a niche optimization — it’s the practical default for any content site large enough that full rebuilds are a real cost. Used well, paired with on-demand revalidation for time-sensitive content, it closes the gap between static performance and dynamic freshness almost entirely.

  • Stop Hydration Mismatches in Next.js: A Practical Guide to SSR Stability

    Stop Hydration Mismatches in Next.js: A Practical Guide to SSR Stability

    The Misunderstood Middle Step

    On the surface, SSR looks simple: the server renders HTML, the browser receives it, and users see content immediately. But between “server renders HTML” and “user can interact with the page,” there’s a critical phase that almost nobody talks about in interviews—and almost everybody gets wrong in production.

    That phase is **hydration**.

    Hydration mismatches are responsible for some of the most frustrating and hard-to-debug performance regressions I’ve encountered. They’re also one of the hidden reasons why technically “SSR’d” sites still fail Core Web Vitals audits.

    > If you haven’t yet read SSR: The Non-Negotiable Standard for SEO Performance.

    What Is Hydration, Exactly?

    When Next.js renders a page on the server, it produces a static HTML string and sends it to the browser. That HTML is immediately visible — no JavaScript required to see it.

    But that HTML is inert. It has no event listeners. Clicking a button does nothing. Forms don’t submit. Dropdowns don’t open.

    **Hydration** is the process where React takes that server-rendered HTML and “attaches” the JavaScript to it — making it interactive. React walks the real DOM (the HTML the browser received) and the virtual DOM (what React thinks the page should look like), and reconciles them.

    Server HTML (static) + React runtime = Interactive page

    In Next.js, this happens automatically after the JavaScript bundle is downloaded and parsed.

    Why Hydration Errors Happen

    The most common hydration error message in Next.js looks like this:

    Warning: Text content did not match.

    Server: “Monday, April 14” Client: “Friday, April 17”

    Or the more alarming:

    Error: Hydration failed because the initial UI does not match

    what was rendered on the server.

    These happen when the **server-rendered HTML doesn’t match what React tries to render on the client**. The DOM tree diverges, and React has to throw away the server HTML and re-render from scratch — defeating the entire point of SSR.

    The most common causes:

    1. Date/time-dependent rendering**

    jsx

    ❌ This will always mismatch

    export default function Header() {

    return <p>Today is {new Date().toLocaleDateString()}</p>

    }

    The server renders the date at build/request time. The client renders a different date (or the same date in a different locale). Mismatch.

    2. `Math.random()`or `crypto.randomUUID()`in render**

    jsx

    Different value on server vs client

    const id = Math.random().toString(36).slice(2)

    3. `typeof window !== ‘undefined’`branching**

    jsx

    ❌ Server gets one branch, client gets another during hydration

    const isClient = typeof window !== ‘undefined’

    return isClient ? <BrowserOnlyWidget /> : null

    4. Browser extensions modifying the DOM**

    Ad blockers, password managers, and translation extensions all modify the DOM after the server delivers it. These trigger hydration warnings that are outside your control — but they’ll still pollute your error logs.

    The Performance Consequence: TBT and INP

    Here’s what most SEO guides miss: hydration isn’t just a developer ergonomics issue. It directly affects your **Core Web Vitals**.

    When React detects a hydration mismatch and falls back to client-side rendering, the browser must:

    1. Discard the existing DOM

    2. Re-render the entire component tree in JavaScript

    3. Repaint the page

    This is CPU-intensive work that blocks the main thread. The result is elevated **Total Blocking Time (TBT)** and worse **Interaction to Next Paint (INP)** — both signals uses to evaluate page experience.

    A page that looks fast (quick FCP from SSR) but feels slow (sluggish interactivity from hydration thrashing) will still lose ground in the rankings to a well-hydrated competitor.

    > This is exactly the rendering problem discussed in “SEO for Software Engineers: Moving from Crawlers to Generative AI. Crawler has grown sophisticated enough to evaluate interactivity, not just initial render speed.

    How to Fix Hydration Issues in Next.js

    Fix 1: `suppressHydrationWarning`for unavoidable mismatches

    For content that genuinely must differ between server and client (like timestamps), suppress the warning at the element level:

    jsx

    <time suppressHydrationWarning>

    {new Date().toLocaleDateString()}

    </time>

    Use this sparingly. It tells React “I know this will mismatch, skip checking this element.” Overusing it defeats the purpose of SSR.

    Fix 2: `useEffect`for browser-only content

    jsx

    import { useState, useEffect } from ‘react’

    export default function ClientDate() {

    const [date, setDate] = useState<string | null>(null)

    useEffect(() => {

    setDate(new Date().toLocaleDateString())

    }, [])

    return <time>{date ?? ‘Loading…’}</time>

    }

    The server renders `null` (or a skeleton). The client fills it in after mount. No mismatch.

    Fix 3: `dynamic()`with `ssr: false`for fully client-side components

    jsx

    import dynamic from ‘next/dynamic’

    const BrowserOnlyChart = dynamic(

    () => import(‘../components/Chart’),

    { ssr: false }

    )

    This tells Next.js to skip rendering this component on the server entirely. It will only hydrate on the client. Ideal for components that use `window`, `document`, canvas, or WebGL.

    Fix 4: Stable IDs with `useId()`

    React 18 introduced `useId()` specifically to generate stable, consistent IDs that match between server and client:

    jsx

    import { useId } from ‘react’

    export default function FormField() {

    const id = useId()

    return (

    <>

    <label htmlFor={id}>Email</label>

    <input id={id} type=”email” />

    </>

    )

    }

    Never use `Math.random()` for IDs in rendered output.

    Partial Hydration: The Next Frontier

    Next.js 13+ with the App Router introduces **React Server Components (RSC)** — a model where some components never hydrate at all. They’re rendered on the server and sent as static HTML with zero JavaScript footprint on the client.

    jsx

    app/page.tsx — This is a Server Component by default

    // It renders on the server, sends HTML, adds NO JS to the bundle

    export default async function Page() {

    const data = await fetch(‘https://api.example.com/posts’)

    const posts = await data.json()

    return <PostList posts={posts} />

    }

    The shift is significant: instead of “SSR everything, hydrate everything,” the new model is “SSR everything, hydrate only what needs interactivity.”

    For SEO, this is transformative. Pages become genuinely lighter — less JavaScript means faster parse time, lower TBT, and better Lighthouse scores — all without sacrificing content visibility for crawlers.

    > For a deeper look at how these rendering strategies affect crawler behavior, see JavaScript SEO: How Search Engine Crawls & Renders JS-Heavy Sites.

    # Checklist: Hydration-Safe Next.js Development

    – [ ] No `Math.random()` or `Date.now()` in JSX render paths

    – [ ] All browser-only APIs wrapped in `useEffect` or guarded with `dynamic({ ssr: false })`

    – [ ] `useId()` used for all generated DOM IDs

    – [ ] `suppressHydrationWarning` used only on genuinely unavoidable mismatches

    – [ ] React 18 App Router adopted for new projects (Server Components by default)

    – [ ] Hydration errors monitored in production (Sentry, Datadog, or `window.onerror`)

    – [ ] Core Web Vitals measured after hydration — not just after FCP

    Summary

    Hydration gets your page interactive for users. Getting hydration wrong means you get the worst of both worlds: the infrastructure cost of SSR with the performance profile of CSR.

    The fix isn’t complicated, but it requires deliberate attention to the boundary between server and client state. Once you internalize that boundary, hydration errors become easy to spot and prevent before they ever reach production — and your Core Web Vitals scores will reflect it.

    FAQ: SSR Hydration in Next.js

    What is hydration in Next.js?

    Hydration is the process where React attaches JavaScript to server-rendered HTML, making the page interactive in the browser. Without hydration, the HTML is static and cannot respond to user actions.


    Why do hydration mismatches happen?

    Hydration mismatches occur when the HTML generated on the server differs from what React renders on the client. Common causes include dynamic values like dates, random numbers, or conditional rendering based on browser-only APIs.


    Are hydration errors bad for SEO?

    Yes—indirectly. Hydration errors can lead to unnecessary client-side re-rendering, which increases Total Blocking Time (TBT) and negatively impacts Core Web Vitals, affecting search rankings.

  • How the Model Context Protocol (MCP) Unlocks Real Business Value in AI

    How the Model Context Protocol (MCP) Unlocks Real Business Value in AI


    To make AI truly valuable—to turn it into an autonomous agent that can analyze your private data, manage your inventory, or automate your workflows—it needs to connect securely to your company’s internal tools and databases. Until recently, building those connections was an expensive, slow, and highly technical nightmare.

    MCP Business Case

    Enter the Model Context Protocol (MCP): a revolutionary new open-source standard that is fundamentally changing how businesses integrate and scale AI.

    The Costly “Integration Bottleneck”

    As an AI Architect working with enterprise clients, I see the same problem repeatedly. A business wants an AI system that can read their live sales data, search through their secure company documents, and automatically update project management tools.

    Previously, achieving this meant we had to build expensive, custom software integrations tied strictly to one specific AI model (like OpenAI or Anthropic). If the company later decided to switch to a newer, cheaper, or faster AI model, all of that costly integration work had to be thrown out and rebuilt from scratch. We were spending more budget on “plumbing” than on actually generating business value.

    What is the Model Context Protocol (MCP)?

    Created by Anthropic (the makers of Claude) and open-sourced for the world, MCP is the solution to this problem. Think of it as the “USB-C cable for AI.”

    Just as USB-C allows you to use the same single cable to connect a monitor, a laptop, or a smartphone, regardless of the brand, MCP provides a universal, standardized way for any AI to securely connect to your business data.

    Instead of paying developers to build deep, fragile connections to specific AI vendors, we simply build an MCP Server for your business. Once that server is built, any modern AI application can plug into it instantly.

    The Real Business Benefits of MCP

    For our clients and enterprise partners, moving to an MCP-based AI architecture delivers massive, immediate ROI:

    1. Enterprise Security and Ultimate Data Privacy

    Security is the number one concern for businesses adopting AI. They fear uploading sensitive corporate data to a public cloud. MCP solves this elegantly.

    An MCP Server can run entirely on your private, secure local network. The AI simply requests the specific answers it needs, and your server grants it access only to the data you permit. Your full database never leaves your secure environment, giving you absolute control over your intellectual property.

    2. Zero Vendor Lock-in (Future-Proofing Your Investment)

    The AI landscape is moving at lightning speed. The best AI model today might be obsolete in six months. By adopting the MCP standard, your business is instantly insulated from vendor lock-in. An integration built today to securely query your CRM can be used by Anthropic today, OpenAI tomorrow, and an entirely new AI startup next year—without rewriting a single line of code.

    3. Eliminating “Hallucinations”

    AI models “hallucinate” (make things up) when they lack facts. MCP allows your AI agents to dynamically pull live, verified facts directly from your business software in real time during a conversation. Because the AI is grounded in your actual, up-to-the-second data, accuracy skyrockets and hallucinations disappear.

    The Future is Seamlessly Connected AI

    We are already seeing an explosion of ready-made MCP connections for tools like Google Drive, Slack, Postgres databases, and GitHub. But the true magic happens when we build custom MCP integrations tailored specifically to your proprietary business data.

    For enterprise leaders and business owners, the directive is clear: stop paying for brittle, vendor-locked AI integrations. By standardizing your AI infrastructure around the Model Context Protocol, you are laying down the tracks for truly autonomous, highly secure, and incredibly powerful Agentic AI.


    Frequently Asked Questions (FAQ)

    What does MCP mean for my current AI investments?

    If you are already investing in AI, shifting your architecture to use MCP protects your investment. It ensures that the tools and data pipelines you build today won’t need to be rebuilt when you inevitably upgrade your AI models in the future.

    Is my business data safe with MCP?

    Yes, arguably safer than traditional methods. Unlike uploading spreadsheets to ChatGPT or Claude where your data leaves your network, your MCP Server acts as a tightly controlled gateway. The AI only “sees” the specific, limited pieces of data it is explicitly granted permission to view by your server.

    Do I need to be using Anthropic’s Claude to use MCP?

    No. While Anthropic introduced the standard, it is completely open-source. A rapidly growing number of AI applications, developer tools, and agent frameworks support MCP, making it a universal standard.

    How does this lower my software development costs?

    Because MCP standardizes how AI talks to databases and APIs, developers only have to write the connection once. They are no longer maintaining multiple different versions of the same integration for different AI vendors, dramatically reducing development and maintenance costs.

  • SSR: The Non-Negotiable Standard for SEO Performance

    SSR: The Non-Negotiable Standard for SEO Performance


    ⚡ The Cost of “Client-Side Only”

    In my career—from REEA Digital to SerpCat and now MonsterClaw—I’ve seen one mistake repeated more than any other: relying on Client-Side Rendering (CSR) for searchable content.

    If your website is just a “blank shell” that waits for JavaScript to load before showing any text, you are gambling with your SEO. While Google can render JS, it does so in a second wave of indexing that can take days or weeks. For enterprise-level SEO, that delay is a death sentence.


    🏗️ Why SSR is No Longer Optional in 2026

    Server-Side Rendering (SSR) means the server does the heavy lifting. When a crawler (or an AI agent) arrives, it receives a fully-formed HTML document.

    The Benefits:

    • Instant Indexing: No “waiting for JS.” All your headers, links, and content are visible on the first pass.
    • Higher Pass Rates for Core Web Vitals: Your Largest Contentful Paint (LCP) is significantly faster when the browser doesn’t have to download, parse, and execute a 2MB JS bundle just to show antag.
    • AI Citations: Large Language Models (LLMs) used for RAG pipelines often prefer clean, semantic HTML over raw JS dumps.

    🛠️ The Headless Advantage with Next.js 14

    In my recent builds, I use a Headless WordPress + Next.js stack. This gives us the best of both worlds:

    1. WordPress: Easy content management for the team.
    2. Next.js (SSR): A high-performance frontend that delivers pre-rendered HTML to the user.

    By using the Next.js App Router, I can ensure that critical sections (like the Blog and AI Projects) are rendered on the server, while interactive elements (like the 3D backgrounds) are hydrated on the client.


    🏁 Final Verdict

    If you care about rankings, visibility, and user experience, you cannot ignore SSR. Don’t build “heavy” websites—build “smart” ones. Let the server do its job so the search engines can do theirs.


    ❓ FAQ: Server-Side Rendering

    Q: Doesn’t SSR use more server resources?
    A: Yes, but the trade-off in SEO value and user retention (due to faster load speeds) far outweighs the marginal increase in hosting costs.

    Q: Can I mix SSR and CSR?
    A: Absolutely. Modern frameworks like Next.js allow for “Partial Prerendering,” where the shell of the page is static/SSR, but interactive components load on the client.

    Q: Is SSR just for big sites?
    A: No. Even a small portfolio benefits. A fast, SSR-powered site tells Google you are a professional who prioritizes accessibility and performance.